
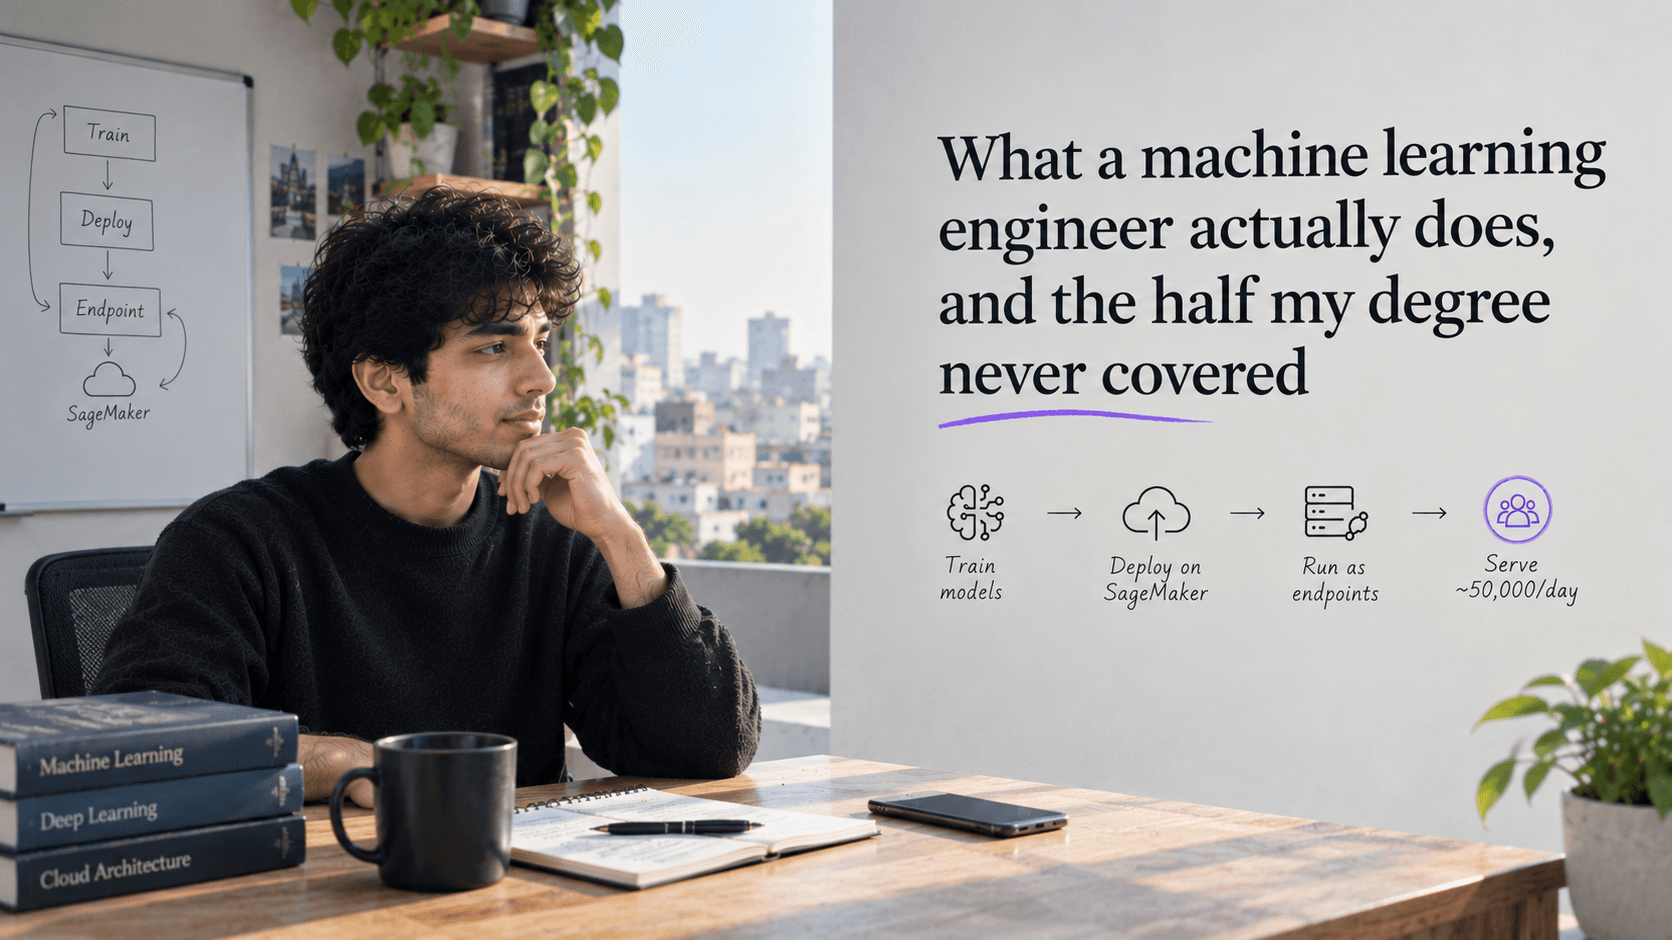
I train models end to end, deploy them, and run them as endpoints on SageMaker. That is the job. I am a machine learning engineer at Revcloud, the systems I look after serve around 50,000 people a day, and my computer science degree prepared me properly for about half of that first sentence.
It prepared me for the models. It did not prepare me for anything that happens after the model works on my own machine. I found that out the first time somebody asked me to deploy something.
What does a machine learning engineer actually do all day?
Train a model end to end. Deploy it. Put an endpoint in front of it on SageMaker so other systems can call it. Keep all of that running.
Look at how little of that is the part students picture. The picture most people have of machine learning is choosing an architecture and watching the loss come down. That part is real and I do it. But a model that only exists in a notebook is not serving anyone. Turning it into something that answers a request from another system is a separate skill, and it is most of the week.
So what did the degree actually give me?
The basics, and the core principles of machine learning. I want to be straight about that, because "university taught me nothing" is a popular line and it is not true.
Those principles are the part that does not go out of date. Frameworks change, the cloud provider changes, the fashionable architecture changes every year or two. Knowing why a model behaves the way it does carries across all of it. You cannot pick that up from a tutorial in a weekend, and it is the thing I would least want to be missing.
So the degree was not wrong. It was incomplete, in a specific and predictable way.
What does deploying a model actually involve?
The task I was given was to build complete pipelines from scratch, training and deployment both.
The training half was fine. I knew how training works and I could build that whole pipeline. Then I reached the word deployment and realised I did not know what it meant. Not in the sense of having read about it and never tried it. I could not have told you what deployment actually is.
Underneath that single word were four questions I did not know existed:
- What deployment is. The plain version, which nobody had ever said out loud to me.
- How you deploy a production grade model, as opposed to getting one to run once on your own machine. Those are not the same task and I had only ever done the second.
- What the caveats are. Every one of which I was about to meet in the order that hurt most.
- How to build an MLOps pipeline that redeploys the model and the endpoint by itself when the data updates.
It was overwhelming. That is the accurate word and I am not going to dress it up, because pretending otherwise would be useless to anybody reading this who is about to feel the same thing.
The fourth one is the one I would go back and tell myself about first. At university a model is an artifact. You train it, you evaluate it, you hand it in, it is finished. In production it is not an artifact, it is a process.
The data keeps changing, so the model has to keep being rebuilt and redeployed, and something has to do that without a person remembering to. Nothing in a degree prepares you for that, because coursework has a submission date and production does not.
I learned all of it at work, under a deadline, which is the most expensive classroom available. AWS publishes its own documentation on deploying models for inference, and it was free the whole time I was at university. Nothing stopped me reading it two years earlier except not knowing I needed to.
What should you study while you are still at university?
Find out what work is actually being done in the industry, how it is done, and then learn to do it yourself. That is the whole of my advice, and the three parts are in that order for a reason.
Most students skip the first part entirely. They study what is in front of them and assume the syllabus is a description of the job. It is not. It is a description of the foundations, which is a different thing, and nobody at the university is going to tell you where it stops.
Finding out what the work looks like is not hard. Read job posts for the roles you want and notice which words keep appearing that nobody has taught you. Read the documentation for the tools those posts name. Look at what engineers complain about publicly, because people complain in detail about the parts of a job that are real.
Then do the third part, which is the one that counts. Take the smallest model you can train and put it somewhere a request can reach it. It does not need to be good. It needs to exist outside your laptop. You will hit every one of the three gaps above in an afternoon, and you will hit them while nothing is at stake.
That last point matters more than it sounds. I have sat on the hiring side of about twenty technical interviews, and the fastest way to lose one is to claim something you cannot support when somebody asks a second question about it. "I have deployed a model" is a sentence worth being able to say truthfully. It is also, on its own, more than a lot of graduates can say.
I made the same discovery from the other direction when my first job offer came from talking about real users rather than React. The pattern is the same one. What gets you hired, and what gets you through the first month, is the part of the work that no course assigns.

Machine Learning Engineer · Revcloud
I'm a machine learning engineer at Revcloud. I build the ML systems that serve about 50,000 people a day, plus the AWS and Azure infrastructure they run on. I finished my computer science degree at COMSATS in 2025, but I'd already been working as an engineer since my second year. I've also sat on the other side of the interview table for around twenty candidates in backend, AI and web roles. Most of what I write here comes out of that.